Agent Reach is an open-source tool (MIT, 89k stars) that gets your AI assistant online with a single command — reading YouTube transcripts, searching Xiaohongshu, and parsing Reddit without paid APIs. It fixes the classic agent blind spot: great at writing code, useless at reading webpages. For Claude Code, Cursor, and OpenClaw users tired of the 'can't fetch that' wall.
In a nutshell: This open-source tool (MIT license) with 89k stars solves the headache of getting your AI assistant online with a single command. Just copy the install link to your agent, and within minutes it can read YouTube transcripts, search Xiaohongshu, and parse Reddit discussions—no paid APIs or custom web scrapers required.
The Pain Point: Agents Can Write Code, But They Can’t Read Webpages
When you ask Claude Code, Cursor, or a self-hosted OpenClaw instance to look something up, it often hits a wall:
- Watching a YouTube tutorial → Can’t fetch captions.
- Searching Twitter reviews → Twitter API requires a paid plan; the free tier is practically useless.
- Finding real-world troubleshooting posts on Reddit → Anonymous endpoints return 403 errors, and server IPs get blocked outright.
- Checking Xiaohongshu word-of-mouth reviews → Login is strictly enforced, locking out guests.
- Summarizing Bilibili videos → yt-dlp is completely blocked by Bilibili’s 412 anti-scraping measures.
- Ordinary webpages → Scraped content returns a mess of raw HTML tags that are impossible to parse.
Every platform has its own gatekeeper. Spending half an afternoon installing tools, tweaking cookies, and testing proxies gets old fast.
How Agent Reach Solves This
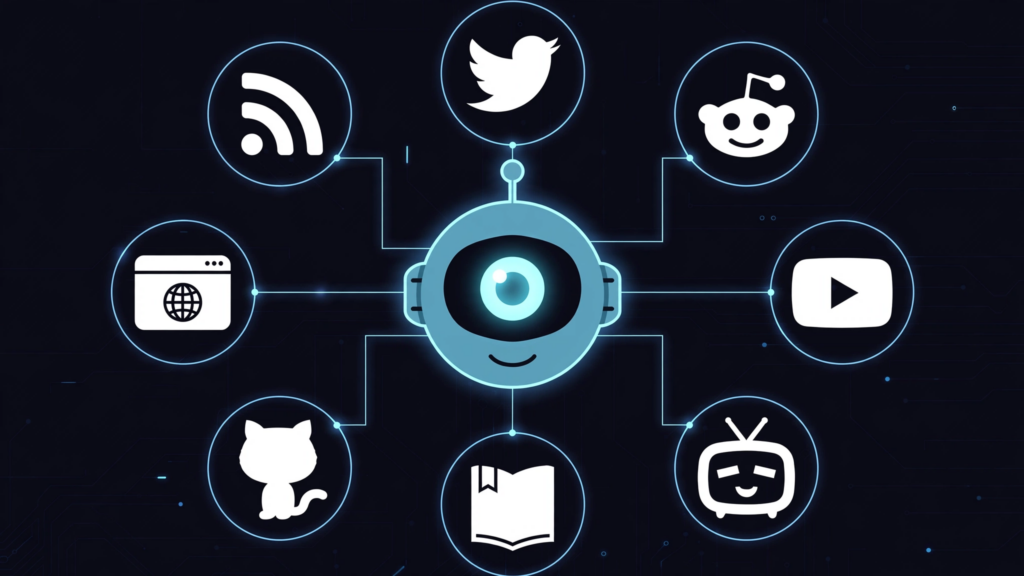
Rather than just being another scraper, Agent Reach acts as a capability layer that automatically selects, installs, and health-checks integration methods for you.
Each platform relies on a prioritized “primary + fallback” ordered list, automatically failing over if one path breaks. The agent-reach doctor command tells you instantly which routing path each platform is taking, whether it’s operational, and how to fix it if it’s broken.
It currently supports 13 platforms, with 6 ready to use out of the box:
| Platform | Status | How to Use |
|---|---|---|
| Webpages, YouTube Subtitles, RSS | Zero-config | Ready to read immediately |
| Exa Web Search, Public GitHub Repos, V2EX, Bilibili Search | Zero-config | Bilibili search requires no login |
| Twitter/X, Reddit, Facebook, Instagram | Unlocked via config | Reuses existing Chrome login state (Desktop OpenCLI) |
| Xiaohongshu (RED) | Unlocked via config | OpenCLI uses active Chrome session or Cookie-Editor export |
| LinkedIn, Boss Zhipin, Xueqiu, JustPod Podcasts | Unlocked via config | Install on demand |
This neatly complements our previous site projects: WeKnora turns local documents into a queryable knowledge base by feeding data inward, whereas Agent Reach searches for data outward. And for the recurring 404 RSS errors on YouTube covered in n8n + OpenClaw YouTube Intelligence Center, extracting subtitles directly via Agent Reach is far more reliable.
Getting Started in Three Steps
1. Give the installation link to your agent
Send this prompt inside Claude Code, OpenClaw, or Cursor:
Help me install Agent Reach: https://raw.githubusercontent.com/Panniantong/agent-reach/main/docs/install.mdThe agent will read the installation guide, download the tool, and run a diagnostic check. By default, it runs in safe mode—only checking for missing environment dependencies without modifying your system. It will only execute a real installation with --system once you explicitly grant permission.
Manual installation works too (pipx is recommended to avoid PEP 668 errors):
pipx install https://github.com/Panniantong/agent-reach/archive/main.zip
agent-reach install --env=auto          # Diagnostic check only
agent-reach install --env=auto --system # Real installation after confirmation
agent-reach doctor # Check status of all channelsNote for OpenClaw users: Enable exec permissions before installing, otherwise the agent won’t be able to run commands like pip install. Claude Code and Cursor have no such restrictions.
2. Tell the agent which extra channels you need
The basic 6 channels work right after installation. If you also need Xiaohongshu, Twitter, or Reddit, simply say, “Help me configure Xiaohongshu and Twitter.” The agent will guide you through the process platform-by-platform: setting up desktop OpenCLI and reusing your active Chrome login state without ever requiring you to hand over your passwords.
3. Use natural language directly
No commands to memorize. Armed with the bundled SKILL.md file, the agent automatically knows what to call:
- “Check what this YouTube video is about” → Automatically extracts subtitles.
- “Search Bilibili for AI tutorials” → Executes
bili search, no login required. - “Check Reddit to see if anyone else has run into this error” → Routes through the configured login-state backend.
- “Search the web for a comparison of LLM frameworks” → Uses Exa semantic search, API key-free.
Hardware & System Requirements
Requirements are very lightweight since it essentially stitches existing open-source tools together:
- Python 3.10+, Node.js, gh CLI (GitHub’s official command line tool).
- Supports Windows, macOS, and Linux. Windows caveat: Avoid the Microsoft Store fake alias for
python3—usepy -3or the actual installation path. Previous UTF-8 encoding garble issues on Chinese Windows environments have been fixed. - Local machines do not need a proxy. Servers require one, but a basic residential proxy running about $1 a month is plenty (as explicitly noted in the README).
- RAM and disk space usage are practically negligible; heavy lifting is handled by upstream tools like yt-dlp, bili-cli, OpenCLI, and feedparser.
Frequently Asked Questions
Is it completely free?
A: The core tool and upstream dependencies are entirely open-source, and services like Exa and Jina Reader operate within free tiers. The only potential cost is a server proxy; running locally costs zero.
Why did Bilibili drop yt-dlp?
A: Real-world testing in mid-2026 revealed that Bilibili’s 412 anti-scraping filters completely block yt-dlp access. Rotating proxies and adding cookies proved useless, rendering it obsolete here. Bilibili searches now route through bili-cli for search and details, while subtitles rely on OpenCLI.
Why does Reddit require a login?
A: Anonymous endpoints have been entirely locked down by Reddit, and developer APIs require manual approval, leaving login-state routing as the only viable path. Desktop setups use OpenCLI to mirror your active Chrome session for reddit.com, while server setups use rdt-cli + Cookies.
Are cookies safe? Will my account get banned?
A: Cookies are stored strictly local at ~/.agent-reach/config.yaml with 600 permissions and are never uploaded. Official warning: Use a burner account, never your main one. Automated script calls differ from organic browsing behavior, carrying a residual risk of platform flagging.
How does this differ from writing your own MCP plugins?
A: As covered in our previous post Connecting Local LLMs to MCP Services, MCP solves “how models call tools.” Agent Reach solves “where tools get data from.” The former handles protocol translation, while the latter handles channel selection and maintenance, keeping the most stable access methods up-to-date across various platforms for you.
Limitations
Not all 13 platforms work out of the box. Only 6 are genuinely zero-config; platforms like Reddit, Xiaohongshu, and Twitter require extra login setup. The 2026 version officially retired three broken channels—Douyin, Weibo, and WeChat Official Accounts—due to severe anti-scraping measures or upstream abandonment. The maintainers prefer removing them over leaving broken, pseudo-working integrations.
Integration paths can expire. When platforms tweak their anti-bot measures, certain paths can suddenly break. The project’s strategy involves maintainers actively rolling out backend fixes (such as the wave of single-platform CLI deprecations patched in March 2026). Running agent-reach doctor lets you diagnose and fix issues via prescribed steps, though a channel might experience brief downtime.
Desktop-dependent channels (like the OpenCLI routing for Facebook, Instagram, and Reddit) are poorly suited for headless server environments. Servers should rely strictly on Cookie or MCP workflows.
Untested local edge cases: Native Windows installation end-to-end flows, the actual success rate of OpenCLI installing and covering 5 platforms simultaneously, and Xiaohongshu search return quality. It’s recommended to run agent-reach doctor --json right after installation to check the active_backend status before drawing conclusions.
Who Is This For (And Who Is It Not For?)
Ideal for: Hobbyists running OpenClaw, Claude Code, or Cursor locally who want their AI agents to conduct comprehensive web research, track online reputation, or auto-summarize videos; HomeLab enthusiasts looking to feed extra data sources into n8n and RSS workflows; independent developers who don’t want to pay for Twitter API access.
Not ideal for: Casual users who only chat within the ChatGPT web UI; enterprise users requiring official SLAs or compliance-grade data scraping. The stability of these open-source scraping channels cannot match commercial APIs.
Is It Worth a Try?
Absolutely—provided you are already using AI agents. The core bottleneck has always been that “agents have brains but lack eyes.” Agent Reach slaps those eyes back on with a single command and handles the ongoing maintenance. When a platform blocks a scraper, the maintainers swap out the backend, and you just update with a single command.
Before installing, run agent-reach install --env=auto for a dry-run diagnostic without system modifications to see what’s missing. For platforms requiring login states, always remember to use secondary burner accounts.
Related Links
- Project Repository: https://github.com/Panniantong/Agent-Reach (MIT license, 89k stars, 7 releases, comprehensive Chinese/English README)
- Installation Guide: https://raw.githubusercontent.com/Panniantong/agent-reach/main/docs/install.md
- Related Site Posts: WeKnora Local Knowledge Base, n8n + OpenClaw Intelligence Center