Skip to content

VGoods Lab

  • Home
  • Computers and Servers
  • XR
  • AI and Agents
  • Mobile and wearable devices
  • FlashNote AI

GPU Acceleration

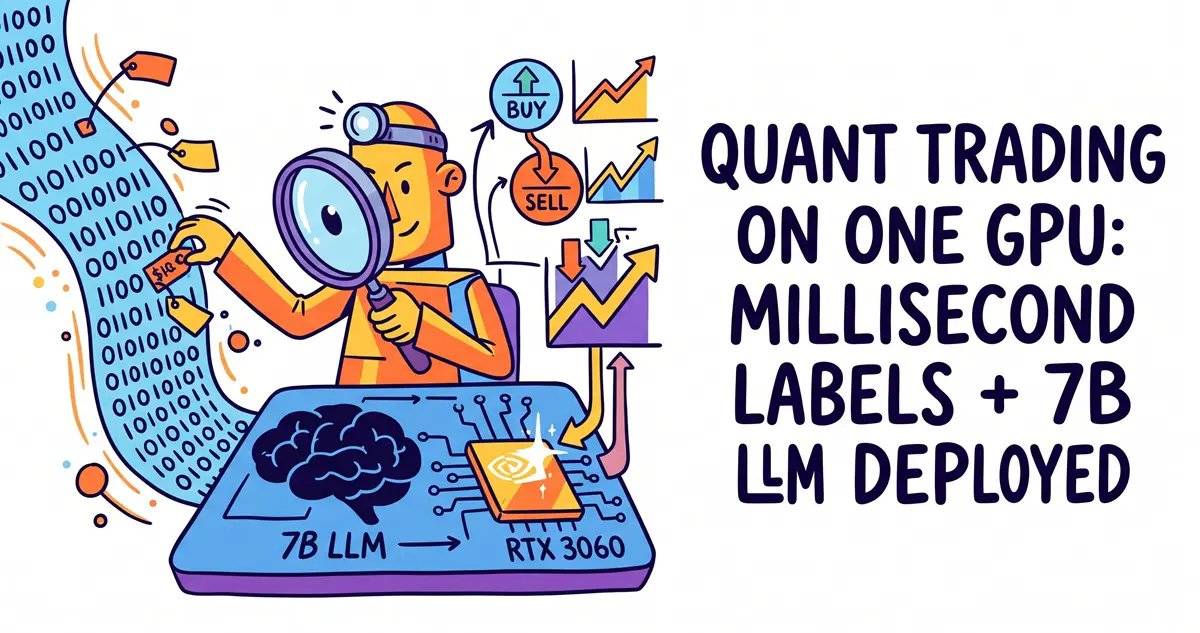
Deploying a Millisecond-Labeling + 7B LLM Dual-AI High-Frequency Quant Trading Stack on a Single RTX 3060
October 19, 2026October 4, 2026 by vgoodslab
Deploying a Millisecond-Labeling + 7B LLM Dual-AI High-Frequency Quant Trading Stack on a Single RTX 3060

Learn how to deploy a millisecond-level Laya fast system and a 7B LLM Kev slow hub on a single RTX 3060 for high-frequency crypto quant trading.
Categories AI and Agents Tags Docker, GPU Acceleration, Homelab, Local AI, Quantitative Trading Leave a comment

The Ultimate Local LLM Deployment Guide: From Bare Metal Builds to Polished AI Powerhouses

October 19, 2026July 7, 2026 by vgoodslab
The Ultimate Local LLM Deployment Guide: From Bare Metal Builds to Polished AI Powerhouses

Unlock local AI power! This guide details LM Studio for beginners, Ollama for automation, and Llama.cpp for advanced users. Run LLMs on your hardware, privacy-first!

Categories AI and Agents Tags GPU Acceleration, Homelab, LLM Deployment, Local AI, Ollama Leave a comment

Recent Posts

  • Did Your AI Agent Actually Do What You Told It To? iFixAi Delivers Independent Agent Audits & Scorecards in 120 Seconds
  • Play Meta Quest Exclusives on PCVR: Getting Started with the AXRB Open-Source Compatibility Layer
  • Batch Produce Videos Without Editing Skills: HyperFrames Renders HTML Directly to MP4
  • Build AI Agents Without Code: Run Docker Agent via YAML and Connect Local Models Without API Keys
  • WSL Native Containers Released: Run Linux Containers on Windows Without Docker Desktop
  • AI and Agents
  • Computers and Servers
  • Mobile and wearable devices
  • XR
  • About
  • Privacy Policy
  • Terms and Conditions
© 2026 VGoods Lab • Built with GeneratePress